Abstract#
Video Diffusion Models (VDMs) can generate high-quality videos, but often struggle with producing temporally coherent motion. Optical flow supervision is a promising approach to address this, with prior works commonly employing warping-based strategies that avoid explicit flow matching. In this work, we explore an alternative formulation, FlowLoss, which directly compares flow fields extracted from generated and ground-truth videos. To account for the unreliability of flow estimation under high-noise conditions in diffusion, we propose a noise-aware weighting scheme that modulates the flow loss across denoising steps. Experiments on robotic video datasets suggest that FlowLoss improves motion stability and accelerates convergence in early training stages. Our findings offer practical insights for incorporating motion-based supervision into noise-conditioned generative models.
The problem: realistic frames, inconsistent motion#
Video Diffusion Models can synthesize high-quality videos across diverse styles and domains. While their outputs are often visually realistic, they frequently lack physical consistency in how things move.
This limits their use in downstream tasks such as robotic manipulation or physics-aware video prediction. Generated sequences are increasingly used as inputs for planning, control, or imitation, so temporally consistent and physically plausible motion matters for these applications.
Flow supervision and noise#
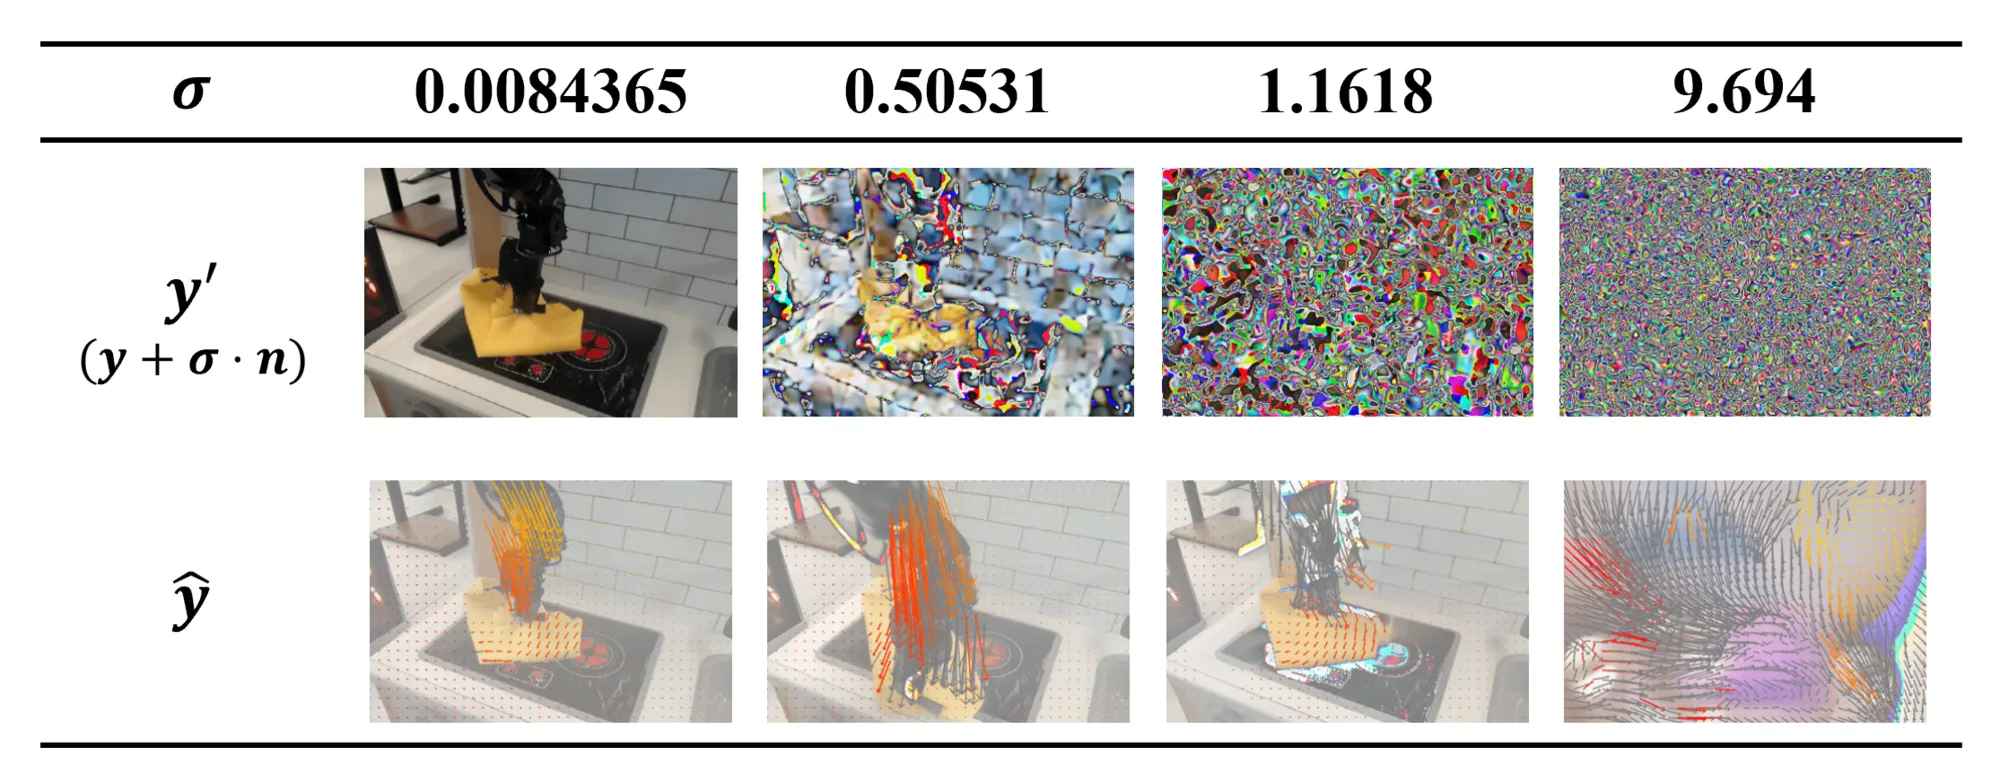
Higher noise scales lead to corrupted inputs and degraded flow extraction, which motivates a noise-aware design of the flow loss.
One possible remedy is to use optical flow, the pixel-level motion field between frames, as a supervision signal.
Prior works incorporate flow either as input conditioning or as a static auxiliary loss. The auxiliary-loss methods typically use pretrained flow extractors in a differentiable but static way, often through image warping between frames to minimize pixel-level discrepancies. They generally do not account for how the reliability of flow varies with noise level during diffusion.
This matters because a diffusion model is trained on inputs across a wide range of noise levels. As the noise level grows, flow extracted from the input degrades, and flow supervision may become unstable or ineffective in high-noise training stages.
FlowLoss: compare flow fields directly, weighted by noise level#
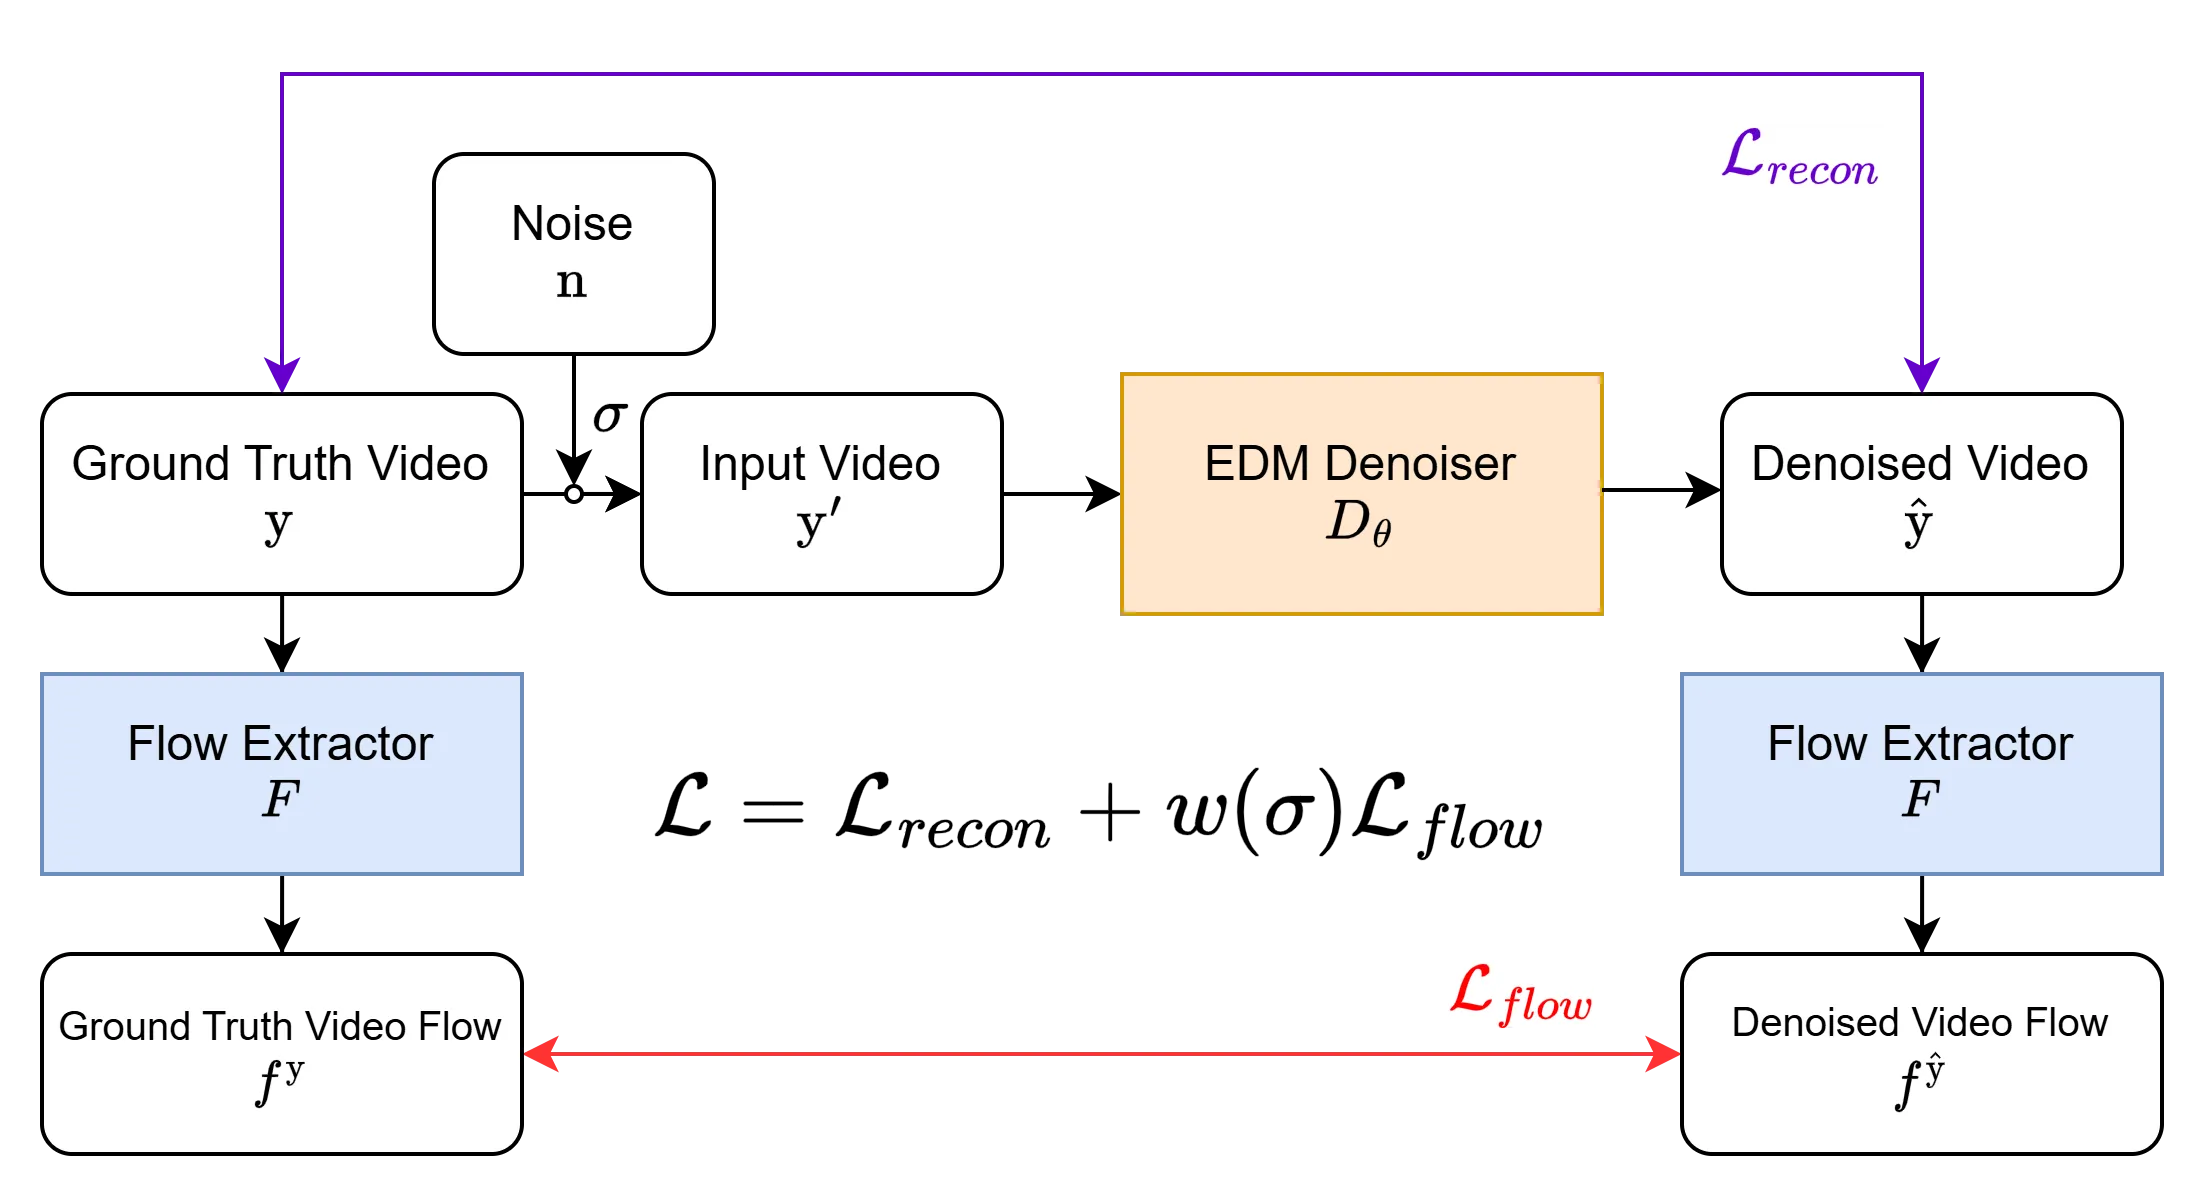
Overview of the FlowLoss supervision framework: the model is supervised by pixel-level reconstruction and by optical flow consistency, with the flow term adjusted by a dynamic weighting .
Instead of warping pixels, we use a pretrained dense flow estimator (DOT) [1] to extract flow from both the ground-truth video and the denoised prediction , and compare the two flow fields directly:
Here and are the flow fields at time , is a binary occlusion mask, and is a global scaling factor that balances the flow and reconstruction losses. The design has three components:
- Differentiable flow extraction. Gradients propagate through both spatial and temporal dimensions, which allows end-to-end training of motion consistency without assuming flow correctness at the pixel level.
- Occlusion weighting. is 1 for visible regions and 0.3 otherwise, which reduces sensitivity to occluded or unreliable regions.
- EDM-style noise weighting. We build on the EDM formulation [2], where the noise level is sampled from a log-normal prior and losses are scaled by .
Since flow predictions degrade with increasing noise, we scale the flow loss by the noise level. To reduce computation, we further adopt a hard gating mechanism , which removes the flow loss when exceeds a threshold :
Because EDM samples from a long-tailed log-normal distribution, many training steps fall into high-noise regimes. The gate applies the flow loss only when flow supervision is likely to be reliable, and focuses its computation on cleaner inputs.
Experimental setup#
We evaluate on Bridge Dataset v2 [3], a large-scale collection of real-world robotic manipulation videos (12,850 training / 1,838 validation / 3,672 test samples, each a natural language task prompt plus 14 resampled frames at 384×256). The VDM is built on the UNet backbone from Stable Video Diffusion 2.1 (Image-to-Video) [4] and is conditioned on the initial frame and the task prompt via cross-attention and FiLM layers [5]. Models are trained on a single NVIDIA H100 GPU for 57,000 steps.
For frame-level fidelity we report FID [6], SSIM [7], PSNR [8], and LPIPS [9]. For temporal consistency we report FVD [10] and the unweighted flow loss.
Results#
| Ground Truth | only | Ours |
|---|---|---|
 |  |  |
Early-stage generation results at step 100. Our method shows improved motion stability and temporal coherence, while the reconstruction-only baseline suffers from spatial drift and jitter.
- Early-stage stabilization. Standard VDMs often produce unstable outputs early in training, especially on fixed-view datasets like Bridge v2, where most pixels are static. In our experiments, FlowLoss yields more stable outputs as early as step 100, which suggests that it helps the model capture the global scene structure more quickly.
- Final metrics. After 57,000 steps, both methods follow similar trends during training, with no consistent advantage at convergence. Our method is marginally better on some metrics and slightly worse on others (see the table below). We attribute this to two possible factors: the hard gate may suppress flow supervision too strongly, limiting its overall influence on learning; and the flow extractor may produce noisy or inaccurate gradients in occluded or low-texture regions.
- Validation curves. Validation FVD and flow loss flatten early, which suggests that flow supervision, when active, may help the model reach a reasonable motion prior more quickly. This could be beneficial for accelerating VDM training or for curriculum-style optimization schedules.
| Method | FID ↓ | SSIM ↑ | PSNR ↑ | LPIPS ↓ | FVD ↓ | Training time |
|---|---|---|---|---|---|---|
| baseline () | 127.6907 | 0.8118 | 28.8986 | 0.0651 | 165.3577 | 07h 56m 47s |
| ours + | 129.1449 | 0.8112 | 29.0284 | 0.0626 | 191.2058 | 08h 45m 08s |
| ours + | 130.1602 | 0.8097 | 28.9757 | 0.0625 | 161.3095 | 10h 31m 28s |
| ours + | 128.6550 | 0.8118 | 28.9896 | 0.0649 | 179.0681 | 14h 29m 26s |
All models are trained for 57,000 steps and evaluated on the test set.
Compared with the baseline, all three FlowLoss settings have slightly higher PSNR and lower LPIPS, and slightly higher FID. FVD is lower only for . The differences are small. Overall, we did not observe a consistent advantage over the baseline at convergence; possible reasons are discussed above. FlowLoss also adds computational overhead: training time increases by roughly 10% to 82% depending on .
Ablation: where in the noise range to apply the flow loss#
| Ground Truth | only | Use | Use |
|---|---|---|---|
 |  |  |  |
Generated videos at 1,600 training steps under the weighted-average formulation. The baseline and the variant are stable, while the variant continues to flicker.
We also explore a weighted-average strategy for combining the two losses:
Unlike the default formulation, which adds the flow loss on top of the reconstruction loss, this design emphasizes one loss depending on . We compare two contrasting schedules: emphasizes flow supervision in the small- (clean input) regime, and emphasizes it in the large- (noisy input) regime.
After 1,600 training steps, both the reconstruction-only baseline and the variant produce stable results with minimal jitter, while the variant continues to produce unstable, flickering outputs. This suggests that applying the flow loss in high-noise regimes may introduce harmful supervision signals due to noisy or inaccurate flow estimates, and it is consistent with our hypothesis that flow supervision is more effective in low-noise stages.
Takeaways#
- Noise level matters for flow supervision. In our experiments, flow supervision was more effective when applied in low-noise stages, where flow extraction is more reliable.
- Direct flow-field matching is a possible alternative to warping-based objectives, and lets gradients propagate through the flow extractor.
- Faster early convergence, at a cost. FlowLoss improved motion stability in early training, but it did not show a consistent advantage at convergence and added computational overhead.
- Future work. Further improvements may be achievable by refining the gating mechanism and exploring more robust flow extractors.
References#
- Guillaume Le Moing, Jean Ponce, and Cordelia Schmid. Dense optical tracking: Connecting the dots. In CVPR, pages 19187–19197, 2024.
- Tero Karras et al. Elucidating the design space of diffusion-based generative models. In NeurIPS, volume 35, pages 26565–26577, 2022.
- Homer Rich Walke et al. BridgeData V2: A dataset for robot learning at scale. In CoRL, pages 1723–1736. PMLR, 2023.
- Andreas Blattmann et al. Stable Video Diffusion: Scaling latent video diffusion models to large datasets. arXiv:2311.15127, 2023.
- Ethan Perez et al. FiLM: Visual reasoning with a general conditioning layer. In AAAI, volume 32, 2018.
- Martin Heusel et al. GANs trained by a two time-scale update rule converge to a local Nash equilibrium. In NeurIPS, volume 30, 2017.
- Zhou Wang et al. Image quality assessment: From error visibility to structural similarity. IEEE Transactions on Image Processing, 13(4):600–612, 2004.
- Alain Horé and Djemel Ziou. Image quality metrics: PSNR vs. SSIM. In ICPR, pages 2366–2369, 2010.
- Richard Zhang et al. The unreasonable effectiveness of deep features as a perceptual metric. In CVPR, pages 586–595, 2018.
- Thomas Unterthiner et al. Towards accurate generative models of video: A new metric & challenges. arXiv:1812.01717, 2018.